



Virtual Screening
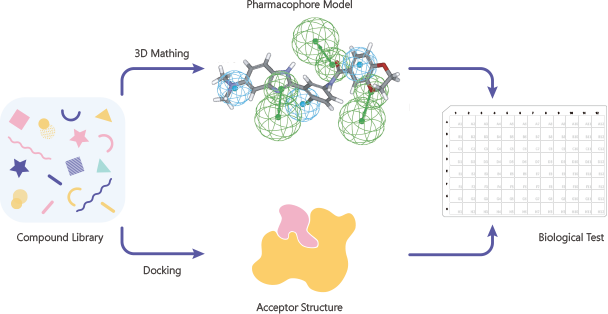
In the last decades, high-throughput screening (HTS), which refers the experimental screening of large libraries of chemicals against a biological target, plays a crucial role in the identification of new lead compounds in the early-stage drug discovery. However, HTS requires expensive equipment and facilities, and its success depends on the size of the compound library. The high cost and low hit rate associated with HTS have stimulated the development of in silico virtual screening (VS). Virtual screening is a computational technique used to search libraries of small molecules in order to identify those structures which are most likely to bind to a drug target. Nowadays, it has become a crucial step in early-stage drug discovery owing to its unique advantages over experimental HTS: drug target-relevant, competitive price and efficient.
MedChemExpress (MCE) provides high quality virtual screening service that enables researchers to identify most promising candidates. Based on the laws of quantum and molecular physics, our virtual screening services can achieve highly accurate results. Our optimized virtual screening protocol can reduce the size of chemical library to be screened experimentally, increase the likelihood to find innovative hits in a faster and less expensive manner, and mitigate the risk of failure in the lead optimization process.
Publications Citing Use of MCE Virtual Screening (Part)
- Signal Transduct Target Ther. 2025 Oct 7;10(1):333.
- Circulation. 2025 Sep 23;152(12):882-898.
- Cell Death Differ. 2025 Apr;32(4):613-631.
- Adv Sci (Weinh). 2025 Aug;12(31):e14902.
- Adv Sci (Weinh). 2025 Jul 17:e07167.
- Adv Sci (Weinh). 2025 Jul 16:e17278.
- Nat Chem Biol. 2025 Jun 2.
- Theranostics. 2025 Mar 18;15(9):4188–4211.
- Environment International 198 (2025) 109442
- Cell Death Dis. 2025 Apr 29;16(1):351.
- NPJ Biofilms Microbiomes. 2025 Mar 7;11(1):40.
- Nat Commun. 2024 Jan 2;15(1):9.
- Nat Commun. 2024 May 17;15(1):4216.
- Adv Sci (Weinh). 2024 Oct;11(39):e2402115.
- Adv Sci (Weinh). 2025 Feb;12(6):e2410525
- Theranostics. 2024 Jul 1;14(10):3984-3996.
- J Hematol Oncol. 2022 Jul 14;15(1):93.
- Theranostics. 2022 Sep 6;12(15):6509-6526.
- Cancer Lett. 2022 Oct 10:546:215851.
- J Transl Med. 2024 Feb 21;22(1):192
Types
The virtual screening methods are mainly divided into two types: structure-based virtual screening (SBVS) and ligand-based virtual screening (LBVS).
• SBVS
The general scheme of a SBVS strategy starts with processing the 3D target structural information of pharmaceutical protein interested (determined either experimentally or computationally through homology modeling) and then dock the small molecules to targeted binding sites. These docked compounds are then ranked based on their predicted binding affinity or complementarity to the binding site, as well as other criteria. Usually only a few top-ranked compounds are selected as candidates for further experimental assays. Our fast and accurate ligand docking and scoring procedures lead to efficient virtual screening.
• LBVS
In the absence of 3D structures of potential drug targets, LBVS is one of the most popular approaches for drug discovery and lead optimization. Biological data are explored in order to identify known active or inactive compounds that will be used to retrieve other potentially active molecular scaffolds for experimental evaluation. LBVS methods include approaches such as similarity and substructure searching, quantitative structure-activity relationships (QSAR), pharmacophore mapping, and machine learning.
Screening Process
• Target research
• Model building
• Preparation of small molecule compound library
• Molecular docking/pharmacophore mapping
• Scoring/ranking
• Compound selection
Advantages
• Ligand-based and structure-based virtual screening
• Super high-performance computer
• Compound database containing over 16 million purchasable compounds
• 3D pharmacophore model building
• Consideration of water and solvation effects

Compound Databases
| Cat. No. | Name | Size | Description |
|---|---|---|---|
| HY-L001V | MCE Bioactive Compound Library | 34,325 | A unique collection of 34,325 bioactive compounds including natural products, enzyme inhibitors, receptor ligands, and drugs for high throughput screening (HTS) and high content screening (HCS). |
| HY-L032V | MCE Fragment Library | 42,200 | A unique collection of 4,0000+ fragment compounds for high-throughput screening (HTS). |
| HY-L0113V | 1M Drug Fragment-Based Diversity Library | 1,000,000 | A diversity compound library contains 1,000,000 compounds with drug fragments. Each compound has at least one drug fragment. These selected molecules have 702,902 Bemis-Murcko Scaffolds (BMS) with drug-like chemical space. This library is highly recommended for AI-based lead discovery, ultra-large virtual screening and novel lead discovery. |
| HY-L0120V | Asinex BioDesign Library | 170,269 | “BioDesign” approach incorporates key structural features of known pharmacologically relevant natural products (e.g. alkaloids and other secondary metabolites) into synthetically feasible medicinal chemistry scaffolds. In order to identify the privileged pharmacophores, ring systems and linkers, we have carried out statistical analysis of structural features of natural products, marketed drugs, and drug candidates. Saturated, fused ring, spiro, and bridged systems with a tendency towards multiple chiral centers are highly privileged among natural products and marketed drugs yet these structures are very poorly represented in commercial libraries. This library addressed this market need by incorporating these privileged elements into the design of novel synthetic molecules with high molecular framework diversity, multiple stereogenic centers (≥2), and degree of saturation (Fsp3 > 0.5). |
| HY-L0122V | Asinex CNS Macrocycles Library | 1,122 | Several CNS multi-parameter scoring approaches have been reported: CNS-MPO, CNS-MPO V.2, CNS-TEMPO, which suggesting an algorithm to predict CNS-ike properties of new chemical entities. We have applied these scoring algorithms to select macrocycles satisfying multiple cut-offs and structural desirability criteria. The resulting set consists of 1,122 macrocyclic compounds with CNS-MPO > 4, CNS-MPO.v2 > 4, and CNS-TEMPO < 4 for CNS-related drug discovery and research. |
| HY-L0118V | Asinex Covalent Inhibitors Library | 942 | A unique set of molecules containing mild electrophilic moieties that covalently interact with amino acid residues in the target protein. The diversity of our compounds for covalent drug discovery ranges from natural product-like scaffolds to macrocycles, creating multiple opportunities in hit generation for a selected target. |
| HY-L0117V | Asinex Macrocycles for Glycomimetics Library | 1,412 | Glycomimetics are designed to mimic the structure of natural carbohydrates and modulate their disease-related functions. Macrocyclic glycomimetics are an extremely interesting class of glycomimetics as they occupy space between small and macro molecules. Macrocyclic glycomimetics are mostly represented by naturally occurring molecules derived from marine microorganisms and bacterial or fungal metabolites. |
| HY-L0116V | Asinex Macrocycles for RNA Library | 1,065 | Macrocycles are promising scaffolds for the design of novel RNA targeting molecules. This collection of macrocycles for RNA consists of very diverse, drug-like molecules which incorporate certain known RNA-recognition elements (e.g. nucleobase ring systems and analogs) distributed within macrocyclic rings or peripheral fragments. As macrocyclic molecules tend to be larger than traditional screening molecules, it is vital to carefully assess and control their physicochemical properties. All macrocycles have been tested for aqueous and DMSO solubility with cutoffs applied at 10 mM in DMSO and 50 µM in PBS (pH 7.4); PAMPA permeability has also been tested for representative set of macrocycles. |
| HY-L0115V | Asinex Macrocycles Library | 10,091 | ASINEX has elaborated a library of diverse macrocycles using an effective tool box of synthetic methods. The resulting scaffolds are novel, tremendously diverse, medchem-relevant, macrocyclic frameworks. Macrocyles tend to be larger than traditional screening molecules which make them perfect discovery tools for targets with shallow or extended binding sites. At the same time, their unique character based on restricted flexibility and ability to form intra-molecular hydrogen bonds allows for design approaches effectively optimizing properties such asaqueous solubility and membrane permeability. Many of these macrocycles have been tested for aqueous and DMSO solubility with cut-offs applied at 10 mM in DMSO and 50 µM in PBS (pH 7.4) followed by PAMPA permeability assay. |
| HY-L0119V | Asinex PPI Pre-Plated Library | 3,253 | Protein protein interactions (PPI) have pivotal roles in life processes. The studies showed that aberrant PPI are associated with various diseases. However, the design of modulators targeting PPI still faces tremendous challenges, such the difficult PPI interfaces for the drug design, lack of ligands reference, lack of guidance rules for the PPI modulators development and high-resolution PPI proteins structures. The PPI Library comprises molecules of various sizes, frameworks, and shapes ranging from fragment-like entities to macrocyclic derivatives designed as secondary structure mimetics or as epitope mimetics. The designs cover β-turn / loop mimetics and α-helix mimetics. Since helices present at the interface in 62% of all protein-protein interactions. This library focused on designs including mimics with the substitution geometry of an a-helices, as well as designs that mimic the location of “hot-spot” side chains in helix-mediated PPIs. |
| HY-L0124V | Chemspace CNS-Focused Library | 13,082 | The basic requirements for the compounds that are supposed to penetrate the blood-brain barrier are somewhat different from those for the majority of drug discovery projects. Alongside the known problem with delivery of the large and non-polar compounds and their penetrability through the cell membrane, the other issue arises as well: small and polar compounds are not able to pass the Blood-Brain Barrier. Chemspace CNS-focused library comprises quite small, non-polar compounds that are also free from PAINS/toxic fragments and aggregators. |
| HY-L0091V | Chemspace Lead-Like Compound Library | 1,367,511 | Chemspace Lead-Like Compound Library contains 1,367,511 in-Stock lead-like compoundswith favorable physicochemical profiles and high Quantitative Estimation of Drug-likeness. |
| HY-L0093V | Chemspace Scaffold derived set | 10,119 | Diversity-based screening continues to be a vital tool for drug discovery. Efficiency and productivity can be improved by using screening libraries that offer maximum diversity whilst retaining drug-like properties. Chemspace Scaffold derived set composes 10,119 compounds, which including 3,373 scaffolds, 3 compounds per each. This library has exceptional coverage of drug-like chemical space. |
| HY-L0094V | Chinese National Compound Library | 1,398,968 | The Chinese National Compound Library (CNCL) composes 1.4 million compounds possessing diversified structures. Coupled with this library will be advanced sample handling, information management and quality control systems. Most compounds in the library are drug-like, conforming to “Lipinski’s Rule of Five”, such as MW < 500, logP < 5, Hydrogen Bond Donors < 5. |
| HY-L0101V | FCH Group Screening Library | 2,244,487 | FCH Group Screening Library Collection contains about 2,244,487 lead-like compounds for biological screening. This brand new collection comprises polar molecules with pharmacologically important groups such as free carboxylic and amino groups. |
| HY-L0105V | InterBioScreen Synthetic Compounds Library | 485,000 | InterBioScreen Synthetic Compounds Library contains about 485,000 immediately available compounds. The library is generated by very rigorously selecting the most interesting classes of compounds that are most likely to become new drugs or plant protection agents or veterinary preparations. |
| HY-L932V | Kinase Macrocyclic Compound Virtual Library | 2,000,000 | Macrocyclic compounds (≥12-atom cyclic small molecules/peptides) have unique physicochemical properties. They form preorganized conformations with high binding affinity/selectivity, target traditional small-molecule-inaccessible proteins, and bridge small-molecule drugs and biological agents. As key protein phosphorylation enzymes, kinases are linked to tumors, COPD, etc., and are critical therapeutic targets. Traditional small-molecule kinase inhibitors lack selectivity, causing off-target toxicity, low bioavailability, and acquired resistance. Macrocycles’ semi-rigid structure restricts conformations, boosts binding selectivity, optimizes pharmacokinetics, and makes macrocyclization a core kinase inhibitor optimization strategy. Thousands of bioactive macrocycles were curated from ChEMBL. Via Transformer, macrocyclization was converted into a chemical language translation task, enabling end-to-end macrocycle generation from linear precursors with simplified inputs. Macformer achieves efficient, automated linear molecule macrocyclization via deep learning; generated macrocycles have diversity, novelty, biocompatibility, and cover broader chemical space. MCE collected thousands of marketed/clinical kinase inhibitors, using their fragments for macrocyclization to generate derivatives. After evaluating synthetic accessibility and physicochemical properties, a million-scale virtual macrocyclic library was built for kinase-related virtual and AI-driven screening. |
| HY-L0088V | Life Chemicals 50K Diversity Library | 50,240 | Life Chemicals presents a number of exclusive Pre-Plated Diversity Sets composed of 50,240 novel compounds with optimal physicochemical properties selected from Life Chemicals collection of newly synthesized items by dissimilarity search with an average Tanimoto threshold of 82%. These Diverse Screening Sets are ideal starting points for customers looking for a wide range of dissimilarity to screen against a number of targets from different classes or where little information is available on targeted protein structure. |
| HY-L0123V | Life Chemicals CNS Focused Screening Library | 30,300 | The incidence and significance of central nervous system diseases are increasing at an alarming rate all over the world. Although substantial research efforts have been applied to develop new CNS-active drugs, only a few CNS disorders are addressed satisfactorily, while the remaining ones pose significant clinical challenges. Blood-brain barrier (BBB) permeability is one of the most important limiting factors in the design and development of novel CNS-targeted pharmaceuticals for the treatment of neurological disorders. Carefully selected from the HTS Compound Collection to meet the parameters optimized for high BBB-permeability, our CNS Focused Screening Library comprising over 30,300 structurally-diverse and potentially CNS-active screening compounds. This original Screening Compound Library is aimed at supporting CNS drug design projects and HTS efforts in search for novel neurotherapeutics. |
| HY-L0087V | Life Chemicals HTS Compound Collection | 503,810 | Life Chemicals Collection of small organic molecules for high-throughput screening currently contains 503,810 off-the-shelf products. The Collection is being permanently replenished with de novo designed products having optimal physicochemical parameters for drug discovery. |
| HY-L0107V | Life Chemicals Natural Product-like Compound Library | 13,236 | Natural products are small molecules produced naturally by any organism including primary and secondary metabolites. Nowadays, new drugs based on Natural products are successfully applied to treat tumors, viral and bacterial diseases, and nervous disorders. In response to the current drug discovery demand, we created this natural product-like compound library with 13,236 in-stock synthetic compounds similar to natural ones. The library was designed by 2D fingerprint similarity filtering, chemical descriptor-based and natural-likeness scoring selection. These compounds are useful tools for high throughput screening (HTS) and high content screening (HCS) programs. |
| HY-L0121V | MCE 10K Natural Product-like Compound Library | 10,000 | Natural products are an attractive source with varied structures that exhibit potent biological activities, and desirable pharmacological profiles. The core scaffold of a natural product can also provide a biologically validated framework upon which to display diverse functional groups. Inspired by bioactive natural products, natural product-like compounds, occupying the same chemical space, are ideally suited to explore and to facilitate understanding of biological pathways. MCE 10K Natural Product-like Compound Library consists of 10,000 natural product-like compounds. Each compound has scaffold of natural products or Tanimoto coefficient >0.6 with natural products. The natural-likeness scoring of these compounds is >-2. What’s more, compounds in the library are drug-like and readily available for re-supply, making it a powerful tool for new drug research and development. It can be widely applied in high-throughput screening (HTS) and high-content screening (HCS). |
| HY-L0129V | MCE Virtual Screening Compound Library1 | 2,000,000 | A collection of over 2 million screening compounds from manufacturers such as VitasM, Specs, Otava and more, available at competitive prices, suitable for virtual screening and AI-driven screening applications. |
| HY-L0130V | MCE Virtual Screening Compound Library2 | 10,000,000 | A collection of over 10 million screening compounds from 18+ manufacturers. The data has been cleaned, suitable for virtual screening and AI screening. |
| HY-L910V | MegaUni 50K Virtual Diversity Library | 50,000 | MegaUni 50K Virtual Diversity Library consists of 50,000 novel, synthetically accessible, lead-like compounds. With MCE's 40,662 Building Blocks, covering around 273 reaction types, more than 40 million molecules were generated. Based on Morgan Fingerprint and Tanimoto Coefficient, molecular clustering analysis was carried out, and molecules closest to each clustering center were extracted to form a drug-like and synthesizable diversity library. The selected 50,000 drug-like molecules have 46,744 unique Bemis-Murcko Scaffolds (BMS), each containing only 1-3 compounds. This diverse library is highly recommended for virtual screening and novel lead discovery. |
| HY-L0095V | OTAVAchemicals Screening Collection | 270,000 | OTAVAchemicals Screening Collection contains about 270,000 re-supply compounds for prompt delivery. All compounds have undergone quality control to confirm their chemical structures. |
| HY-L0114V | Pharmeks Screening Compound Library | 439,804 | This library contains about 439,804 natural and synthetic screening compounds. The information in the database includes logP, H-bond donors, H-bond acceptors, rotable bonds. |
| HY-L0086V | Specs HTS Compounds Library | 200,382 | A unique collection contains 200,382 diverse chemical compounds to pharmaceutical and biotechnology scientists for drug discovery. |
| HY-L0104V | UORSY New Generation Screening Library | 1,900,000 | UORSY New Generation Screening Library contains about 1,900,000 compounds. The library is a revolutionary collection of lead-like molecules with outstanding structural quality and diversity—New Generation Screening Library (NGSL). Its core is decorated with interesting building blocks, including important medicinal fragments such as peptide bonds, amino groups and hydroxyl groups. and designed for discovery of new Voltage-gated calcium channel blockers. |
| HY-L0103V | UORSY Screening Library | 680,000 | UORSY Screening Compounds Library contains about 680,000 compounds. The library has extensively developed a polymerization synthesis method that provides a highly diverse chemical structure. More than 85% of the compounds in the library have drug-like physicochemical properties, and more than 35% of the compounds have lead-like properties. |
| HY-L0096V | Vitas-M Screening Compounds Library | 1,400,000 | Vitas-M Screening Compounds Library (stock) contains about 1,400,000 chemical substances. They are synthetic small molecule organic compounds for biological screening and lead optimization. Select any number of items as a "cherry pick". |
MedChemExpress (MCE) virtual screening services can significantly improve the hit rates and reduce the costs of compound screening. If you have any questions, please do not hesitate to contact us via email [email protected].
バーチャルスクリーニング FAQ
01 バーチャルスクリーニング解析を依頼するために必要な情報は何ですか?
- • タンパク質名および種
- • アミノ酸配列(任意)
- • 三次元構造情報(X線結晶構造、AlphaFold 予測構造など)
- • 既知の活性化合物や結合部位情報(任意)
02 使用できるのはバーチャルライブラリー(品番末尾 V)のみですか?
03 Schrödinger、AlphaFold とは何ですか?
Schrödinger:世界的に標準的な分子シミュレーション・計算化学ソフトウェア。
AlphaFold:Google DeepMind が開発した AI タンパク質構造予測システム。アミノ酸配列から高精度で 3D 構造を予測します。 MCE では AlphaFold 予測構造を用いた VS も対応しています。
04 タンパク質の立体構造情報がない場合(X線構造なし)でも VS を依頼できますか?
05 MCE はいつから VS サービスを開始したのですか?
06 MCE における VS 実績について教えてください。
07 VS の委託では HTVS / SP / XP の全モード使用が前提ですか?追加費用は発生しますか?
08 VS の結果、ヒット化合物が見つからない確率はどれくらいですか?
09 VS ライブラリーのデータセットでは、法規制化合物(毒物など)は除外されていますか?PAINS 化合物は除外されていますか?
- • 法規制化合物・既知毒性化合物:原則として除外済み
- • PAINS 化合物:ライブラリー構築時に積極的にフィルタリング さらに、ドラッグライクネス評価と組み合わせて高品質な化合物セットを提供しています。
10 VS で絞り込まれた候補群に A 化合物が含まれていた場合、A の類縁化合物も同時に候補として出てきますか?
11 データの再現性はどれくらいですか?
12 納期・価格の目安は?モデルケースはありますか?
| The Number of Compounds Screened | Lead Time | Regular VS Price (USD) | Advanced VS Price (USD) | AI Screening Price (USD) |
|---|---|---|---|---|
| 50K | 1-2 Weeks | 1,000 | 2,000 | / |
| 100K | 2-3 Weeks | 1,600 | 3,200 | 4,200 |
| 200K | 3-4 Weeks | 2,200 | 4,400 | 5,300 |
| 300K | 4 Weeks | 2,700 | 5,400 | 6,300 |
| 500K | 4-5 Weeks | 3,600 | 7,200 | 8,300 |
| 1M | 5-6 Weeks | 4,600 | 9,200 | 9,200 |
| 2M | 5-6 Weeks | 6,600 | 12,200 | 12,200 |
| 5M | 5-6 Weeks | 10,000 | 20,000 | 20,000 |
| 10M | 5-6 Weeks | 16,000 | 32,000 | 32,000 |
13 見積りから支払いまでの流れは?
- 1. 相談:ターゲット情報・要望の共有
- 2. 見積り:MCE が評価し正式な見積りを提示
- 3. 確認・契約:合意後に契約締結
- 4. プロジェクト開始:タンパク質準備、化合物準備、ドッキングなど VS 実施
- 5. 納品:化合物構造、スコア、結合様式図などを納品
14 ADME や毒性予測も可能ですか?
15 特定化合物に結合するタンパク質を探索することは可能ですか?
- • 価格:3000 USD
- • 期間:3〜4 週間 です。
16 一般的な研究室の PC(通常の CPU 搭載)で解析は可能ですか?
17 競合メーカー(Enamine)と MCE の VS の違い、立ち位置の違いは?
- Enamine:世界最大級の化合物供給企業。REAL データベースなど、数百万〜数十億規模の化合物空間を保有。 強みは「化合物」。
- MCE:VS、HTS、DEL、生物学評価まで提供する一貫型の薬物探索サービス企業。 200 種以上・約 2800 万化合物のライブラリーを保有し、Schrödinger ベースの専門的 VS を提供。 強みは「サービスとソリューション」。 また、協業により Enamine ライブラリーの利用も可能で、両者は補完関係にあります。